Every business intelligence failure starts the same way: clean-looking dashboards built on data that was never properly prepared. Data transformation is the process that prevents these failures and understanding it is the first step toward building analytics that you can actually trust.
In this article, you’ll learn:
- What is data transformation?
- What are the main types of data transformation?
- How does the data transformation process work?
- What is the difference between ETL and ELT?
- What are the benefits of data transformation for businesses?
- What challenges does data transformation introduce?
- How should you evaluate data transformation tools?
- How do you choose the right data transformation approach?
What is data transformation?
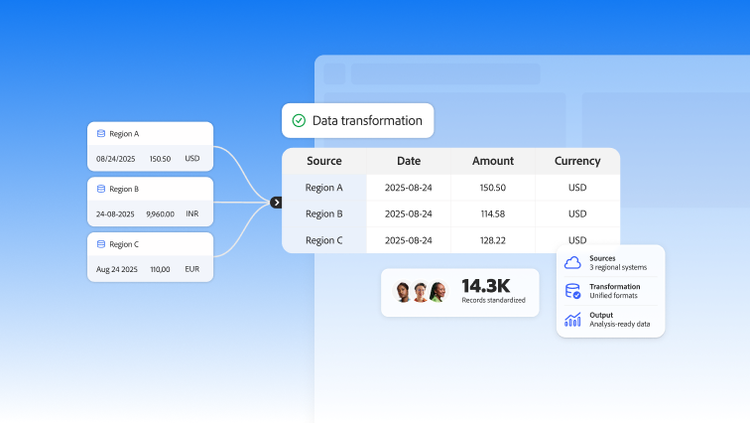
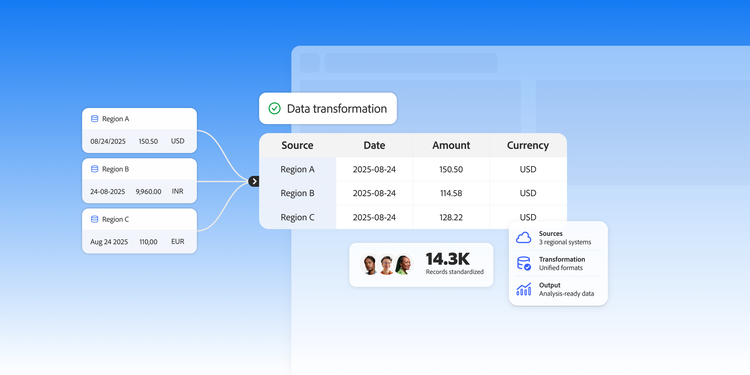
Data transformation is the process of converting raw data from its original format or structure into a clean, consistent format that is ready for analysis or use in downstream systems. Consider a retail company pulling sales records from three regional databases, each using different date formats and currency codes. Before a reporting tool can compare results across regions, the data must be transformed into a single unified schema with standardised dates, a common currency and consistent field names.
Within a broader data pipeline, transformation sits between ingestion (pulling data in) and loading (sending data to a warehouse or analytics platform). Different roles interact with transformation at different points. Data engineers define the rules. Business analysts validate the outputs. Marketing operations teams consume the results in dashboards, segmentation tools and activation platforms.
Transformation becomes critical the moment an organisation operates more than one data source. A single CRM system rarely needs transformation. But the moment that CRM connects to an ad platform, a support ticketing tool and a web analytics system, every field name, data type and record format becomes a potential conflict. Transformation is what resolves those conflicts systematically, not through one-off fixes but through repeatable, rule-governed logic applied every time data moves between systems.
This distinction matters: data transformation is not a one-time clean-up task. It is an ongoing pipeline discipline. Source systems change, new fields appear and formats drift. Organisations that treat transformation as a project rather than a process find their data quality eroding within months.
What are the main types of data transformation?
Data transformations fall into several distinct categories, each solving a specific class of data quality problem. Understanding the types helps teams design pipelines that address all failure modes, not just the obvious ones.
- Normalisation restructures values to a standard scale or format. For example, converting all phone numbers to E.164 format (+1XXXXXXXXXX) ensures that they match across a CRM and a messaging platform. Without normalisation, a customer with the same phone number stored as "+1 555 867 5309" in one system and "15558675309" in another may appear as two different people.
- Aggregation summarises granular records into summary metrics. A finance dashboard that needs daily revenue totals does not want to process millions of individual transaction rows at query time. Rolling up per-transaction revenue into daily totals during transformation makes downstream reporting faster and cheaper.
- Filtering removes records that fail quality or relevance criteria. Excluding test accounts from a customer count before computing a churn rate is a common example. If test accounts are not filtered during transformation, every downstream metric that depends on the customer count is inflated.
- Mapping and field renaming align inconsistent field names across sources. One system shops "cust_id" while another shops "customer_identifier." Transformation maps both to a single canonical "customer_id" so joins and lookups work correctly in the warehouse.
- Enrichment appends additional attributes from a secondary source. Adding firmographic data, like company size and industry to a contact record from a third-party provider is a typical enrichment step. For a deeper look at implementation patterns, see our coverage of data enrichment.
- Anonymisation and masking replace personally identifiable values with tokens or synthetic equivalents. Replacing email addresses with hashed identifiers before sharing data with an analytics vendor is a standard application. For implementation details, see data anonymisation techniques.
- Type conversion changes the data type of a field. Converting a string-formatted date ("2024-01-15") to a proper date type allows a BI tool to sort and filter by calendar period. Without type conversion, date comparisons may fail or produce incorrect sort orders.
Most real-world pipelines apply several transformation types in sequence. A marketing data pipeline might filter bot traffic, map field names, normalise date formats and aggregate data into daily session counts, all before the data reaches a reporting layer.
How does the data transformation process work?
The data transformation process follows a structured sequence of steps. Skipping any step creates downstream errors that are often invisible until a business decision is made using corrupted data. For concrete illustrations of each step in action, see our coverage of data transformation examples.
Step 1: Profile the source data. Before writing any transformation rule, analysts audit incoming data for nulls, duplicates, type mismatches and outliers. A profiling pass on a CRM export might reveal that 12% of records have no email address, that the "state" field contains both abbreviations and full names and that a handful of records have creation dates in the year 1900. Profiling reveals the scope of the problem and informs which transformation types are needed.
Step 2: Define transformation rules. Engineers and analysts jointly specify what "good" data looks like. Rules are documented so they can be applied consistently every time the pipeline runs, not interpreted differently by different team members. For example, a rule might state: "All date fields must be converted to ISO 8601 format (YYYY-MM-DD) in UTC. Records with null email addresses are retained but flagged with a data_quality_warning field set to 'missing_email.'" This step is where data modelling decisions are made because the target schema must be defined before rules can be written against it.
Step 3: Apply transformations. The rules are executed through code (SQL, Python), a visual ETL or ELT tool or a declarative transformation framework. This is where raw data is converted into the target format.
Step 4: Validate the output. Transformed data is tested against expected row counts, value ranges and referential integrity checks. A row-count drop of more than a defined threshold should trigger an alert before data reaches a warehouse. Data validation at this step is what separates a reliable pipeline from one that silently corrupts downstream reports.
The process is not linear in practice. Validation failures loop-back to step 2 for rule revision. Organisations that treat transformation as a one-time project rather than an ongoing pipeline discipline consistently see data quality degrade over time as source systems change and new fields are introduced without corresponding transformation rules.
The key takeaway: transformation quality is determined at the rule-definition stage, not the execution stage. Investing time in step 2 reduces the cost of errors in step 4.
What is the difference between ETL and ELT?
ETL (Extract, Transform, Load) and ELT (Extract, Load, Transform) are the two dominant architectural patterns for running data transformation in a pipeline. The difference is not just sequencing. It has direct implications for cost, latency and team skill sets.
ETL performs transformation before the data reaches the warehouse, in a dedicated processing layer. This pattern is best suited for environments where raw data must never enter the warehouse, whether for compliance reasons, Personally Identifiable Information (PII) sensitivity or because the target system has limited compute capacity. A healthcare organisation that must anonymise patient records before they enter any shared analytical environment is a classic ETL use case. The trade-off is latency: data must be fully transformed before it is queryable, which delays time-to insight.
ELT loads raw data into the warehouse first, then performs transformation inside the warehouse using SQL or a declarative transformation framework. This pattern is best suited for cloud data warehouses like Snowflake, BigQuery or Redshift, where compute is elastic and transformation logic benefits from being version-controlled with the data. Analysts can query both raw and transformed data in the same environment, which speeds up debugging and exploratory analysis. The trade-off is that the warehouse must absorb storage costs for raw data and organisations with strict regulatory requirements around raw data retention may need additional access controls.
The industry has moved toward ELT for most analytical workloads because cloud warehouse compute costs have fallen significantly over the past decade. ETL remains the right choice when transformation logic must run outside the warehouse boundary, for example, when anonymising data before it is allowed to enter a shared environment. Many organisations run a hybrid approach: ETL for sensitive data streams and ELT for everything else.
What are the benefits of data transformation for businesses?
Consistent data quality across systems eliminates the reconciliation of work that typically consumes a large share of an analyst's time. Practitioner estimates commonly place this at 20 to 40 per cent of total analyst hours, though organisations should measure their own baseline before citing a specific figure internally. That time can be redirected toward interpretation and decision support rather than data wrangling.
Transformation enables data from different business functions to be joined and analysed together. A company that has transformed its CRM, ad platform and web analytics data into a common schema can calculate customer acquisition cost at the individual customer level. That calculation is impossible when each system uses a different customer identifier and date format. The ability to join these datasets is a direct product of field mapping, normalisation and data standardisation applied during transformation.
Regulatory compliance is a direct beneficiary of structured transformation. When anonymisation and masking are built into the transformation layer as mandatory steps, every downstream system automatically receives compliant data. This eliminates the risk of an individual analyst forgetting to exclude sensitive fields from an ad hoc export.
Faster, more reliable reporting reduces the time between an event occurring and a business decision being made in response. Organisations that report on yesterday's data rather than last week's data can catch performance issues, such as a declining conversion rate or a spike in support tickets, before they compound into revenue problems.
What challenges does data transformation introduce?
- Schema drift is the most common transformation failure mode in production. When a source system changes a field name, adds a new field or changes a data type without notifying the pipeline team, the transformation rules silently break. Corrupted or missing data reaches the warehouse before anyone notices. The business cost is a report that understates revenue or overstates churn, often for days or weeks before the error is caught.
- Data volume scaling is a challenge that surfaces gradually. Transformation jobs that run acceptably on one month of data begin to fail or time out when applied to three years of history. Organisations that do not design transformation logic for scale from the beginning face expensive pipeline rewrites when data volumes grow and data volumes always grow.
- Governance of transformation rules is an underestimated operational burden. Transformation logic spread across undocumented SQL scripts, spreadsheet formulas and tool-specific configurations becomes impossible to audit, test or hand off. Teams that do not version-control their transformation logic lose the ability to explain why a metric changed between reporting periods.
Data cleansing and data validation must be embedded in the transformation process, not treated as separate upstream activities. When validation is skipped, bad data that passes through transformation appears trustworthy. It is formatted correctly and has the right field names, but the underlying values are wrong. Downstream decisions made using that data carry hidden risk that is difficult to detect after the fact.
How should you evaluate data transformation tools?
Transformation tooling falls into three broad categories, each suited to different team structures and data environments.
- Code-first frameworks use SQL-based or Python-based tools where transformation logic is written as code, version-controlled and tested like software. These are best for teams with engineering capacity that need fine-grained control and auditability. The trade-off is a higher skill floor: business analysts without SQL fluency cannot own or modify transformation logic independently.
- Visual ETL and ELT platforms offer drag-and-drop interfaces where transformation steps are configured rather than coded. These are best for teams where business analysts own transformation logic and engineering resources are limited. The trade-off is reduced flexibility for complex transformations and, in some tools, limited support for version control.
- Embedded transformation in data platforms refers to cloud data warehouses and customer data platforms that include native transformation capabilities alongside storage and compute. These are best for organisations that want to minimise the number of separate tools in their stack. This is most valuable when data modelling, data standardisation and real-time activation are available within the same platform, which can help to reduce pipeline complexity and latency.
Regardless of category, apply these evaluation criteria:
- Does the tool support version control and testing for transformation rules? Transformation logic without version control is a governance risk.
- Does it handle schema changes gracefully or does a source schema change break the pipeline silently?
- Can it scale to the data volumes the organisation will have in two years, not just today?
- Does it produce a documented lineage map showing which source fields produced which output fields? Lineage is required for regulatory audits and for debugging data quality issues.
- What is the total cost of ownership, including computing costs at scale and the engineering time required to maintain the tool?
How do you choose the right data transformation approach?
Use the following decision framework to match your organisational conditions to the right transformation approach.
If your team has engineering capacity and data volumes exceed tens of millions of rows, choose a code-first ELT framework inside a cloud warehouse. This gives you maximum control over transformation logic and the ability to apply software engineering practices like automated testing and peer review.
If your team is analyst-led with limited engineering support and data volumes are moderate, choose a visual ETL platform with built-in connectors for your source systems. This lowers the skill barrier and lets analysts iterate on transformation logic without waiting for engineering sprints.
If you are managing customer data for personalisation and real-time activation across channels, choose a customer data platform with embedded transformation, data standardisation and identity resolution capabilities. Adobe Experience Platform addresses this enterprise-tier scenario where customer data arrives from dozens of sources in incompatible formats, must be transformed and standardised against a common schema in real time and must feed both analytics and activation use cases without duplication. It is one of several enterprise-grade options worth evaluating when those conditions apply, not the default answer for every data transformation need.
If your regulatory environment prohibits raw PII from entering a shared environment, choose an ETL architecture where anonymisation and masking run before data is loaded anywhere.
Before selecting any tool, document your transformation requirements in three dimensions. First, source system count and change frequency, which determine how much schema-drift resilience you need. Second, downstream consumer count, which determines how much governance and lineage documentation is required. Third, latency requirements which determine whether batch transformation is acceptable or whether near-real-time transformation is necessary.
Regardless of the approach chosen, prioritise data hygiene best practices from the first pipeline run. Retrofitting data quality controls into an existing transformation layer is significantly more expensive than building them in from the start.
Frequently Asked Questions
What is the difference between data transformation and data integration?
When should you transform data before loading versus after loading?
How does data transformation affect data quality?
What skills does a team need to manage data transformation?
How is data transformation used in marketing analytics?
Building a reliable data transformation practice is one of the highest-leverage investments a data team can make. For organisations ready to unify customer data across channels with built-in transformation, identity resolution and real-time activation, learn more about Adobe Experience Platform.
Recommended for you
https://business.adobe.com/fragments/resources/cards/thank-you-collections/rtcdp